Mihu Voice is our own speech stack, built for live calls: Umay turns speech into text while the caller is still talking, and Ses turns text into natural speech in seven languages. One API, hosted in Europe or Türkiye, or on your own servers.
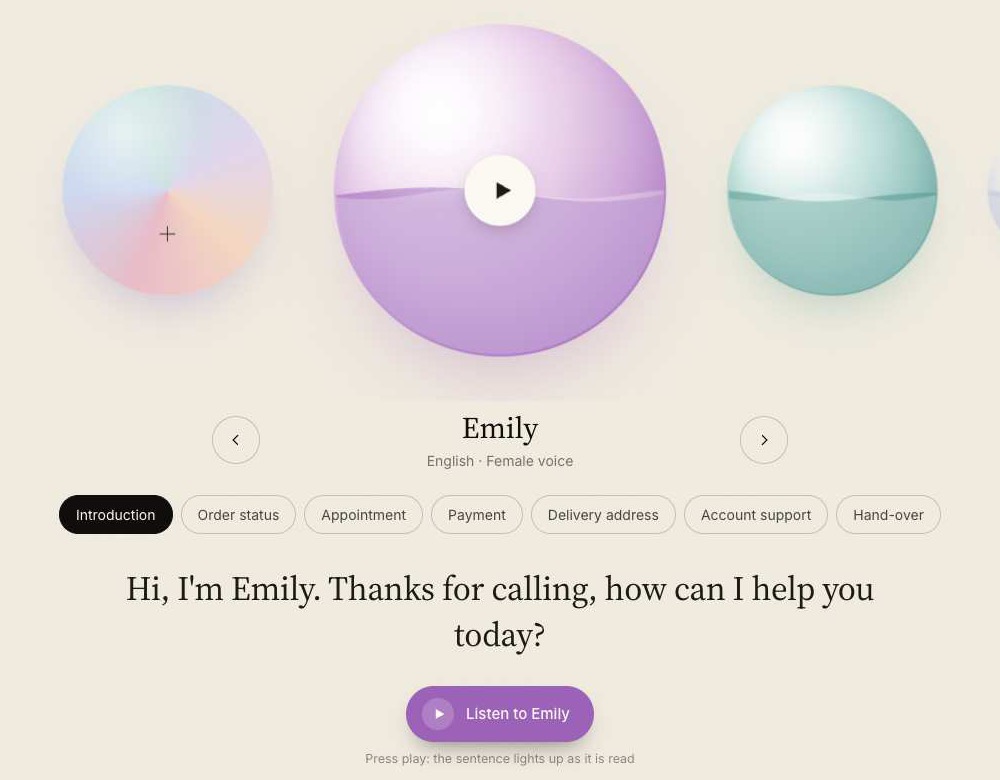
mihu-umay-v1 for speech-to-text and mihu-ses-v1 for text-to-speech sit behind one API key, over REST and WebSocket. Both answer the same way in every region and work with the official OpenAI SDKs by changing the base URL.
Partial text streams in as the person speaks. The final sentence is ready about 80 ms after they stop, quicker than a blink, so your agent can reply without a pause.
On Turkish read speech Umay has a 3.42% word error rate, the lowest of nine systems we tested. In Turkish-only mode one server handles up to 256 live calls.
Speaker options are switched on per request; off means no extra latency.
model=umaymodel=umay-streamwebhook_urlnormalizehints, hint_contextmode=normalgender_detectiondiarizespeaker_lockvoice_isolationreference_voiceprintPOST /v1/voiceprints/verifyPOST /v1/audio/isolationAmounts, dates and plates are written as numbers, adding about 6 ms. Built-in district and neighbourhood lists plus your own hotwords lift live place-name accuracy by 3 to 8 points.
Ses reads addresses, place names, amounts, dates, plates and phone numbers the way people say them, in all seven languages. Audio streams back before the whole sentence is synthesised, and starts in about 0.1 s.
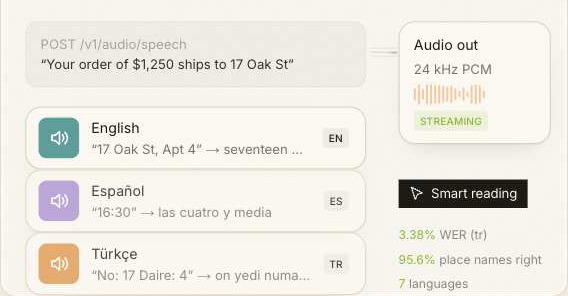
Record a short sample and Ses builds a custom voice you can use next to the 22 built-in ones. Every clone goes through a reading check and needs the speaker’s consent. The recording is used to build the voice and then discarded; only the voice itself is kept.
Clone a voice in the consoleEvery system is scored the same way on public test sets, with numbers and formats normalised. Lower word error rate is better.
| Language | Word error rate | Word accuracy |
|---|---|---|
| Türkçe | 3.42% | 96.58% |
| English | 6.44% | 93.56% |
| Deutsch | 6.46% | 93.54% |
| Français | 6.70% | 93.30% |
| Español | 3.68% | 96.32% |
| Italiano | 3.34% | 96.66% |
| Русский | 5.61% | 94.39% |
| Language | Word error rate | Word accuracy |
|---|---|---|
| Türkçe | 3.38% | 96.62% |
| English | 1.29% | 98.71% |
| Deutsch | 3.62% | 96.38% |
| Français | 4.41% | 95.59% |
| Español | 2.53% | 97.47% |
| Italiano | 3.36% | 96.64% |
| Русский | 5.04% | 94.96% |
Turkish is also measured on phone calls and broadcast media. Methods, every system tested and the full charts are on the benchmarks page. All benchmarks →
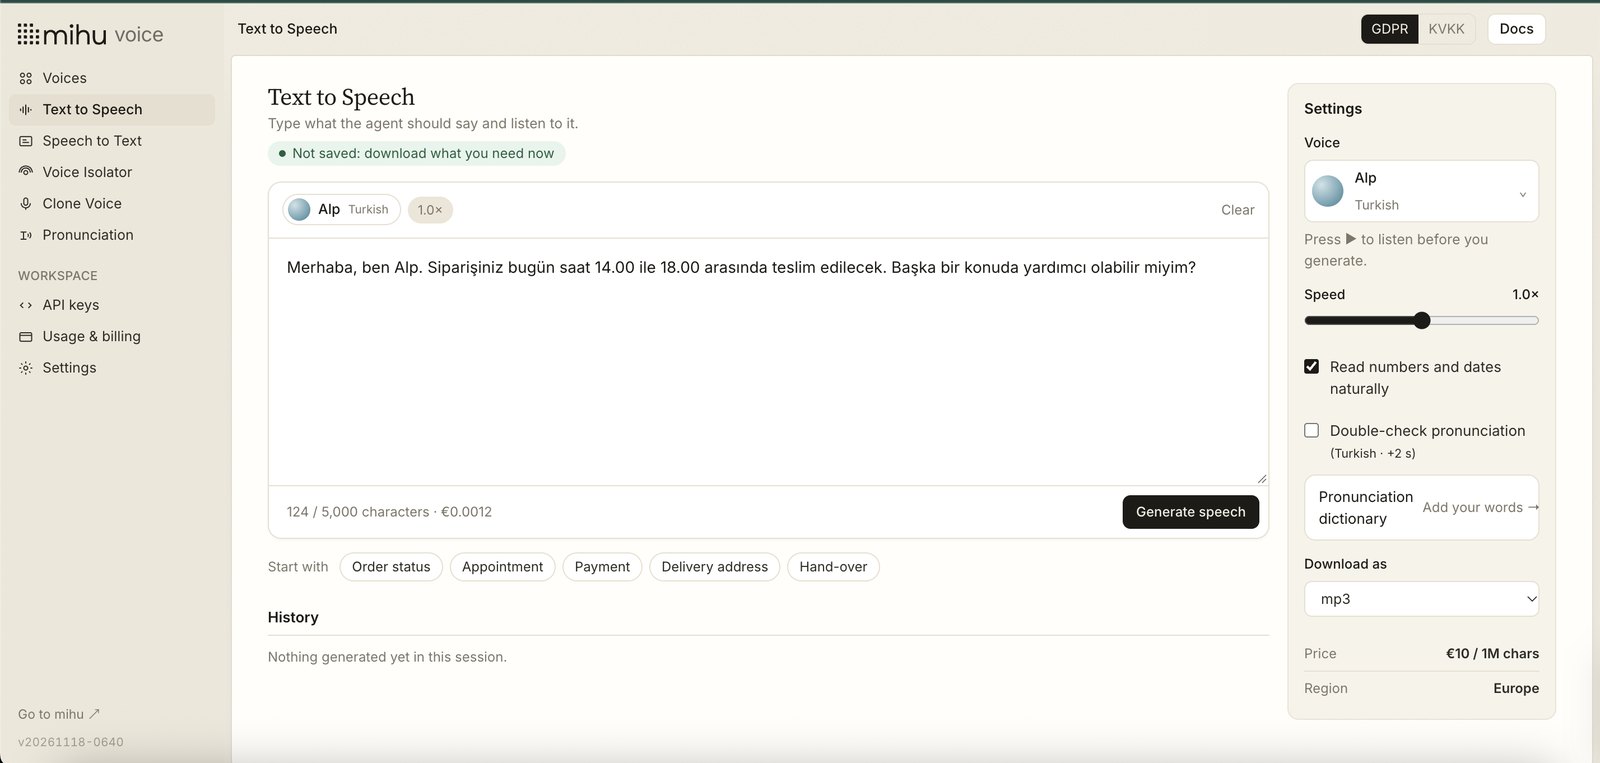
Try voices, transcribe, clone and manage keys without writing code. And you decide how long anything stays.
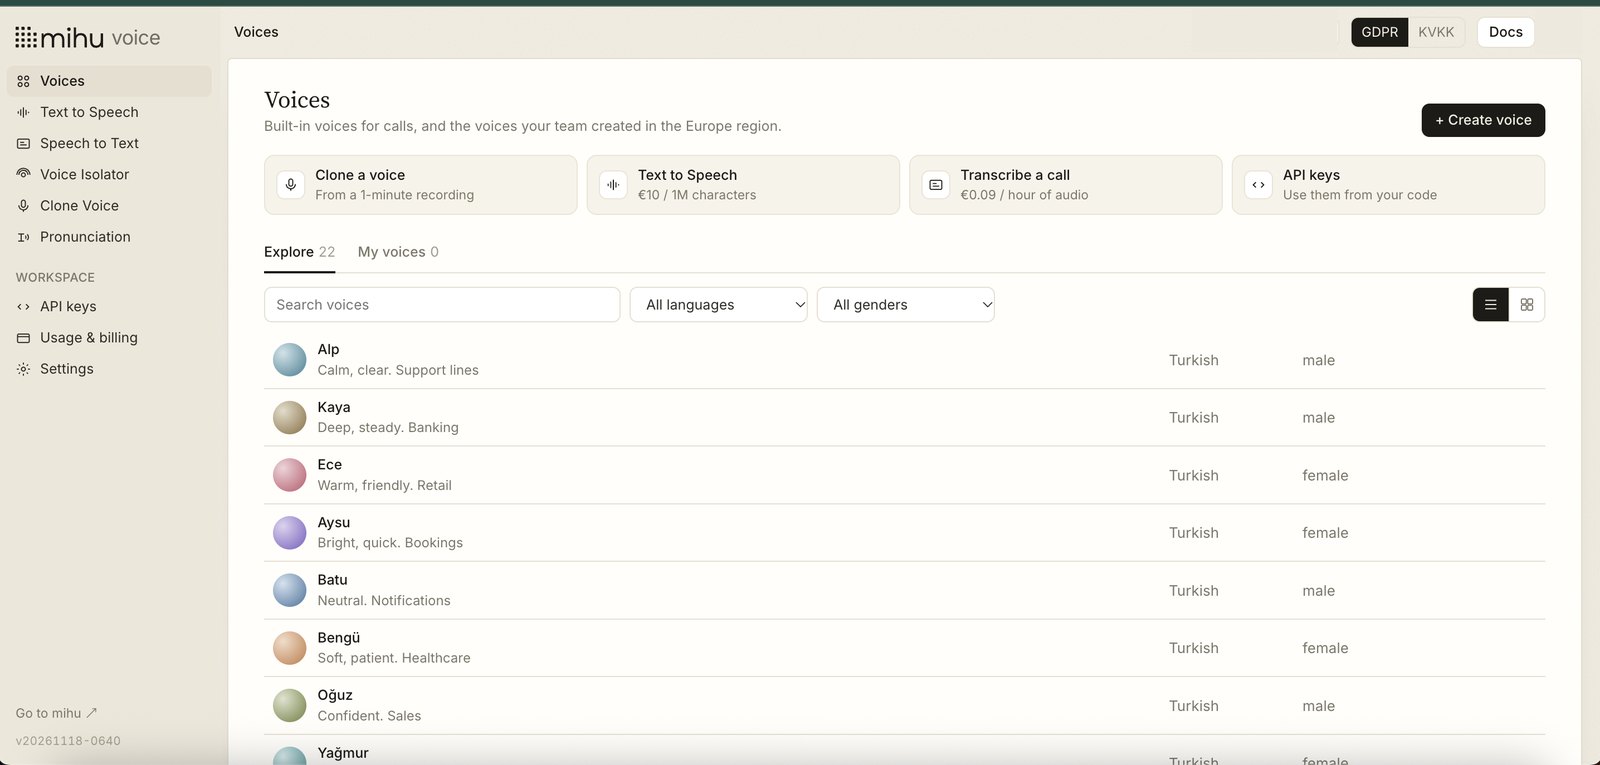
The built-in voices and your own. Listen to any of them before you use it.
Type, pick a voice and hear it start in about 0.1 s. Download as mp3, wav, flac and more.
Upload a file or a link, record, or go live and watch the words appear as you speak.
Remove background voices and noise from a recording; compare before and after.
A voice from 10–30 seconds of speech, with a reading check and the speaker’s consent.
Keys for your servers, quick-start code per region, and what you have spent.
No Mihu SDK is required and nothing runs on your side. Live calls stream audio over a WebSocket; files and synthesis use plain HTTPS. Choosing a region changes only the host.
import asyncio, json, websockets

URL = "wss://stt.eu.mihu.ai/v1/stream?model=umay-stream&language=tr&api_key=KEY"

async def transcribe(chunks):  # 100 ms of 16 kHz mono int16 PCM
    async with websockets.connect(URL, max_size=None) as ws:
        async def read():
            async for m in ws:
                d = json.loads(m)
                if d["type"] == "final":
                    print(d["text"])  # send this to your LLM
        reader = asyncio.create_task(read())
        for chunk in chunks:
            await ws.send(chunk)
        await ws.send(json.dumps({"event": "end"}))
await readerLive streams are processed in memory and never written to disk. A file is held only while it is transcribed.
API results are returned to you, not kept. In the console you choose how long transcripts stay, from not at all to 3 years.
Voice recordings are never stored. Only a numeric signature is kept, and only if you ask for it; it can be deleted for good.
List prices in euros. Options are billed separately, only when you use them. Files and live streams cost the same.
| Workload | Volume | Cost |
|---|---|---|
| Transcribe 10,000 calls of 3 minutes | 500 hours of audio | €45.00 |
| Speak 10,000 replies of 200 characters | 2 million characters | €20.00 |
| Transcribe 1,000 hours of recordings | 1,000 hours of audio | €90.00 |
| 10,000 calls of 3 minutes with speaker diarization | 500 hours + 10,000 conversations | €145.00 |
Running on-prem or at higher volume? Talk to sales →
Listen to the voices, transcribe a call in the console, or get an API key and stream your first audio in minutes.
